🪟 ThinWindow [Claude Code Plugin - Agent Skill - Node.js - Benchmarking]
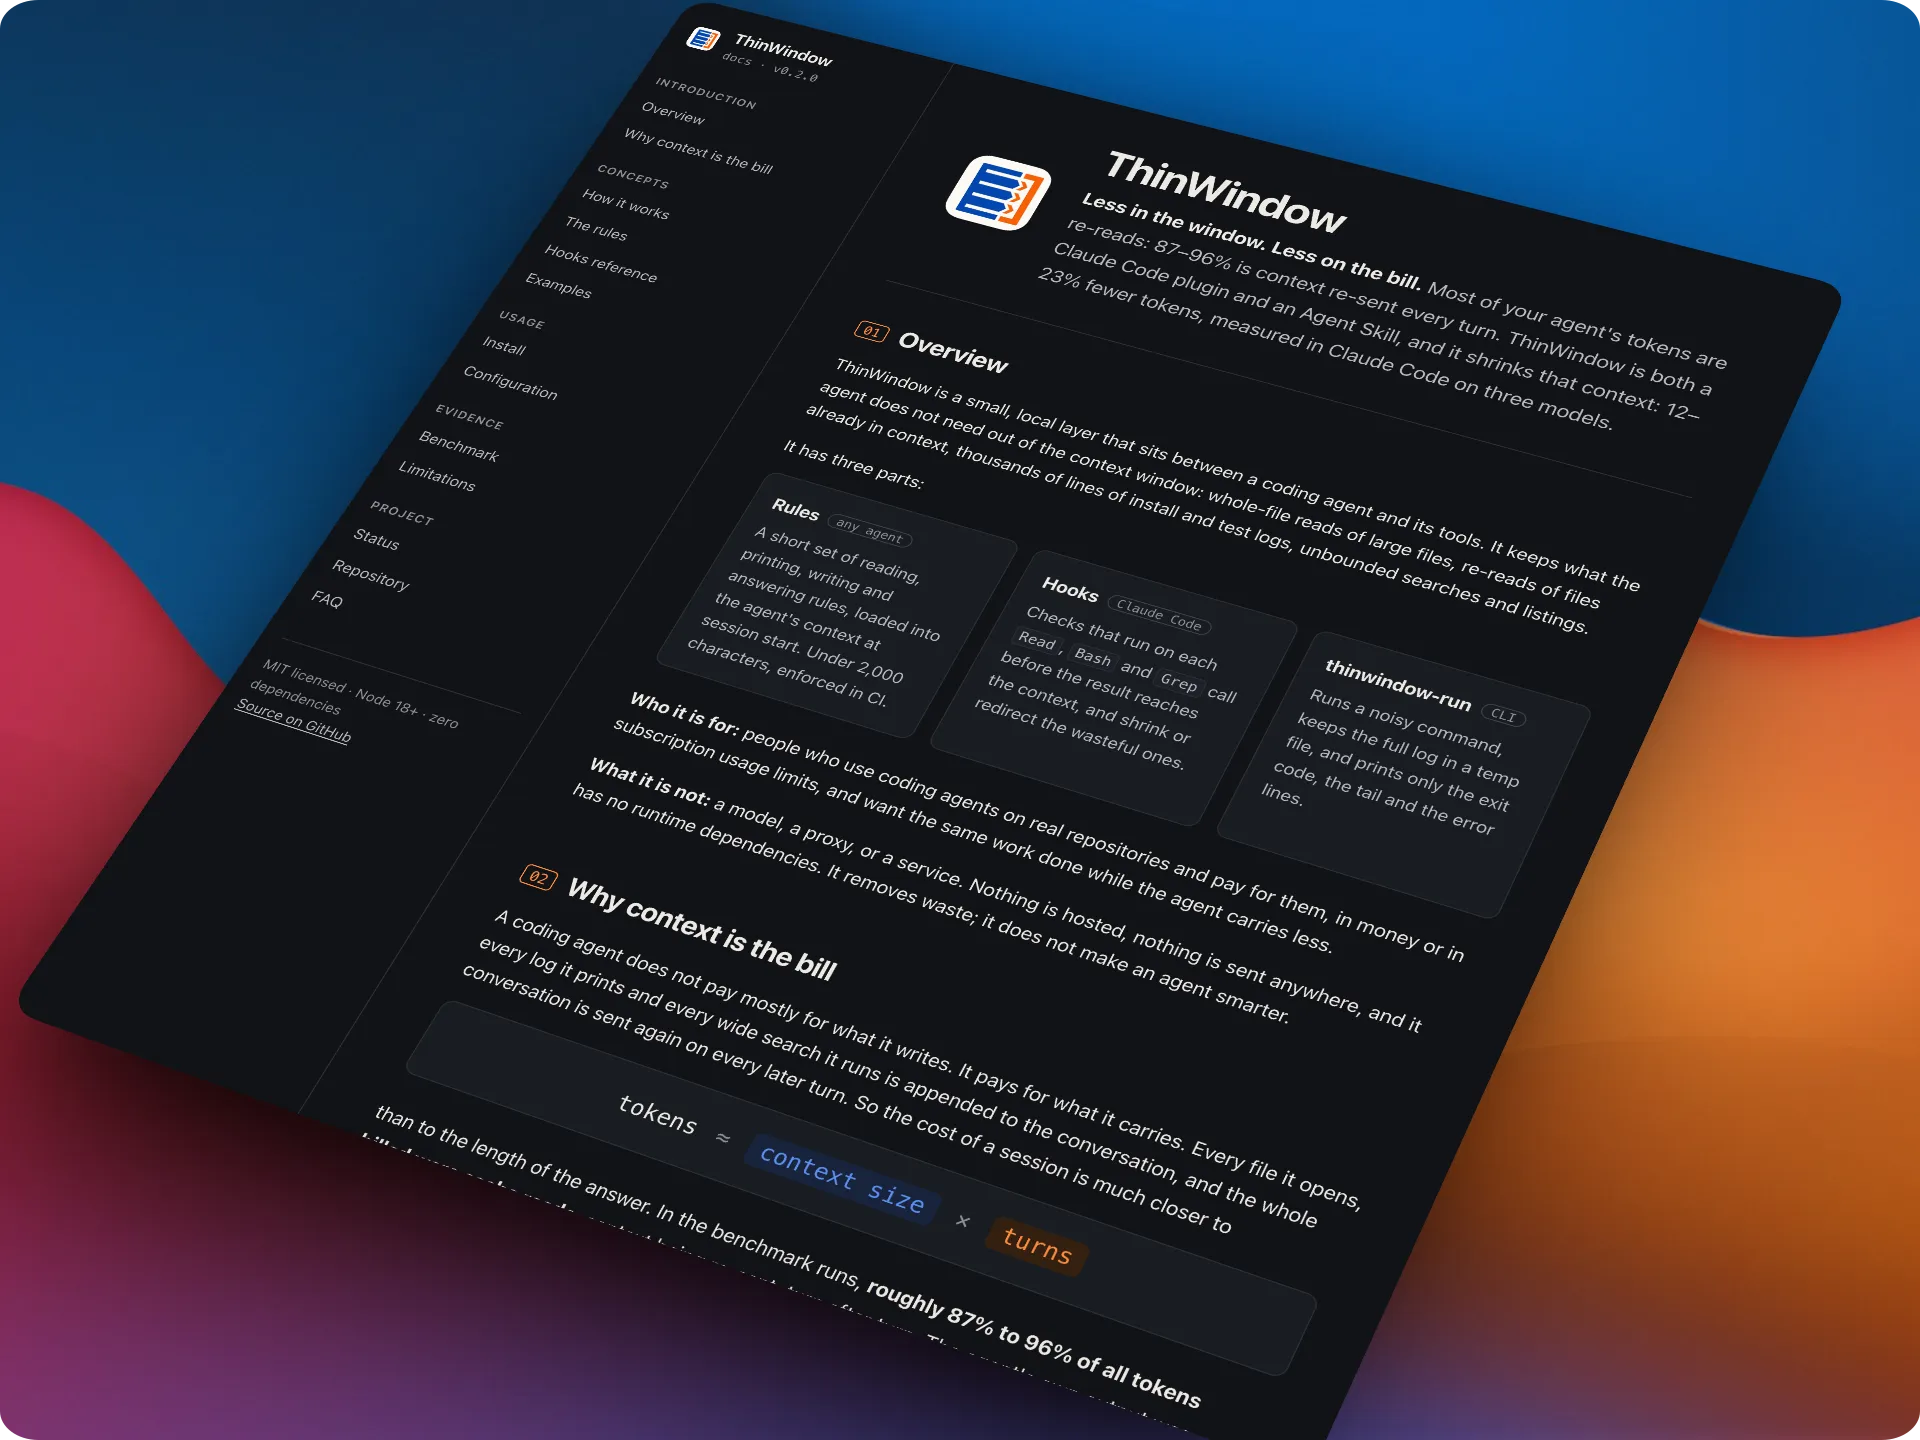
ThinWindow makes coding agents read less. It ships as both a Claude Code plugin and an Agent Skill: a short set of reading rules loaded at session start, plus hooks that enforce the expensive part of those rules at the tool call itself — before a 2,000-line file ever reaches the context window. Across 112 benchmark runs on three models it cut total tokens by 12% to 23% without changing what the agent was able to finish. Zero dependencies, no telemetry, MIT.
View on GitHub DocumentationThe bill is what the agent carries, not what it writes:
A coding agent doesn’t mostly pay for its answers. It pays for its context. Every file it opens, every install log it prints and every wide grep it runs is appended to the conversation — and the whole conversation is re-sent on every turn that follows. The cost of a session is closer to
tokens ≈ context size × turnsthan to the length of the reply. In the baseline benchmark runs, 87% to 96% of every token billed was a cache read: context being re-sent, turn after turn. The agent’s own output was under 2%.
That ratio is the entire argument. Telling an agent to “be concise” trims the ~1% column. Stopping it from pulling a 2,000-line file into the window on turn 3 trims the ~90% one — on that turn and on every turn after it.
Measured on real repositories, published in full:
Each run is one agent solving one task from scratch in a fresh clone of a real open-source repository — click or commander.js — pinned to a commit, with dependencies installed before the agent starts so install logs aren’t billed to either side. The baseline gets plain Claude Code; ThinWindow gets the same plus the plugin. Nothing else differs. A hidden check the agent never sees decides whether the run succeeded.
Measured, not claimed
3 models, 8 tasks, 112 runs, one agent per run — every run recorded, none discarded. ThinWindow cut total tokens by 12% to 23%.
| Model | Tokens | Cost | Success baseline → ThinWindow | Runs |
|---|---|---|---|---|
| Opus 5.5 | −15.8% | −19.4% | 16/16 → 16/16 | 32 |
| Sonnet 5 | −11.6% | −7.4% | 24/24 → 24/24 | 48 |
| Haiku 4.5 | −23.0% | −20.2% | 14/16 → 13/16 | 32 |
Claude Code 2.1.282, measured 2026-09-25. Read straight from the raw benchmark data.
The table above is not a screenshot or a copied number: it is read from the benchmark data in the repository every time this page is built, and again in your browser, so it reflects the latest published run rather than the day I wrote this post.
A skill and a plugin — and why it needs to be both:
These are two layers of the same thing, not two products.
-
The Agent Skill is the instruction layer.
SKILL.mdcarries a rules file kept under 500 tokens: locate withgrepbefore reading, read line ranges instead of whole files, don’t re-read what’s already in context, cap command output, make the smallest change that works, close with three lines at most. It’s portable — any agent that supports Agent Skills installs it withnpx skills add thinwindow/thinwindow, and agents that readAGENTS.mdcan paste the same rules in. -
The Claude Code plugin is the enforcement layer, and it bundles that same skill. On top of the rules, it registers hooks that run on the tool call, before the result reaches the context: a whole-file
Readof a file over 400 lines comes back as the first 120 lines plus a line-numbered outline; re-reading an unchanged file already in context is refused; installs, builds and tests are routed throughthinwindow-run, which sends the full log to a temp file and returns the exit code, the tail and the error lines;catof a lockfile,git logwithout-n,ls -R,treewithout-Land unboundedfindall get a cheaper replacement.
The rules are enforced by hooks rather than trusted to the model because a rule the agent can forget under pressure isn’t a rule. And because the hooks intercept the call rather than correcting the agent afterwards, enforcement costs no turn. Installing the plugin gets you both layers; installing the skill alone gets you the portable half.
Every hook fails open: any error inside ThinWindow lets the tool call through untouched, and repeating a refused call lets it through too, so an agent can never get stuck on it. THINWINDOW=off disables everything.
Install:
# Claude Code — rules and hooks
/plugin marketplace add thinwindow/thinwindow
/plugin install thinwindow@thinwindow

# Any agent with Agent Skills (Codex, Cursor, Copilot, Gemini CLI, OpenCode) — rules only
npx skills add thinwindow/thinwindow
Technical Stack:
- Runtime: Node.js 18+, ESM, zero runtime dependencies. The hooks are local scripts that read a tool call and return a decision.
- Distribution: a Claude Code plugin marketplace, the Agent Skills standard, and a plain
AGENTS.mdadapter. - Benchmark harness: a runner that clones pinned repositories, drives
claude -punder both conditions, runs a hidden verification step and records tokens, cost, turns and the full tool-call trace as one JSON line per run. - Reporting: every published figure — the READMEs, the documentation site and the table on this page — is generated from those raw run files. CI fails if any of them drifts.
- Privacy: no network code at all. No analytics, no crash reports, no update check.
Reproduce it instead of trusting it:
Every run is one line of JSONL in bench/results/, carrying the model, the Claude Code version, the ThinWindow commit, the raw token counts and the tool-call trace. Nothing is excluded: failed runs stay in the tables. To run it against your own account:
node bench/run.mjs --condition baseline,thinwindow --reps 3 --model sonnet --dry-run
node bench/run.mjs --condition baseline,thinwindow --reps 3 --model sonnet --max-cost 10
node bench/report.mjs
What the numbers don’t say:
The benchmark is deliberately published with its limits attached, because a measurement without them is marketing:
- It’s narrow. Eight tasks, two command-line-argument libraries, three models, in JavaScript and Python — and the rules were tuned against those same tasks. That’s enough to show a direction, not enough to promise anyone a percentage.
- Token accounting is volatile. Model versions, harness prompts, cache hit rates, enabled tools, repository size and plain luck can all move a result by more than the effect measured here. That’s why the tables report medians and per-task spread instead of one headline average.
- Not every task improves. On Sonnet 5, three of the eight tasks cost more with ThinWindow than without. Those regressions are published rather than dropped, and they’re the clearest remaining path to better numbers.
- The results will age, and will be re-measured rather than quietly left standing.
Conclusion:
ThinWindow started as a personal tool to make my own agent sessions cheaper, and it was published because the measurements looked more useful than the opinion behind them. The project demonstrates:
- Building against a real cost model — context re-sent per turn — instead of the intuitive one.
- Enforcing agent behaviour at the tool-call boundary through the Claude Code hook API, with a fail-open design that can never block a call.
- Shipping one codebase as both a Claude Code plugin and a portable Agent Skill, so the rules outlive any single harness.
- Designing a reproducible agent benchmark: pinned repositories, hidden verification, sequential runs, raw results committed, regressions included.
- Treating every published number as generated output, with CI failing when documentation drifts from data.
Tags
Share